Veltrix Compute
Compute exists to support the rest of the platform, hosting workloads adjacent to private inference, terminating SD-WAN management planes, and running data-resident workloads where regulators require it.
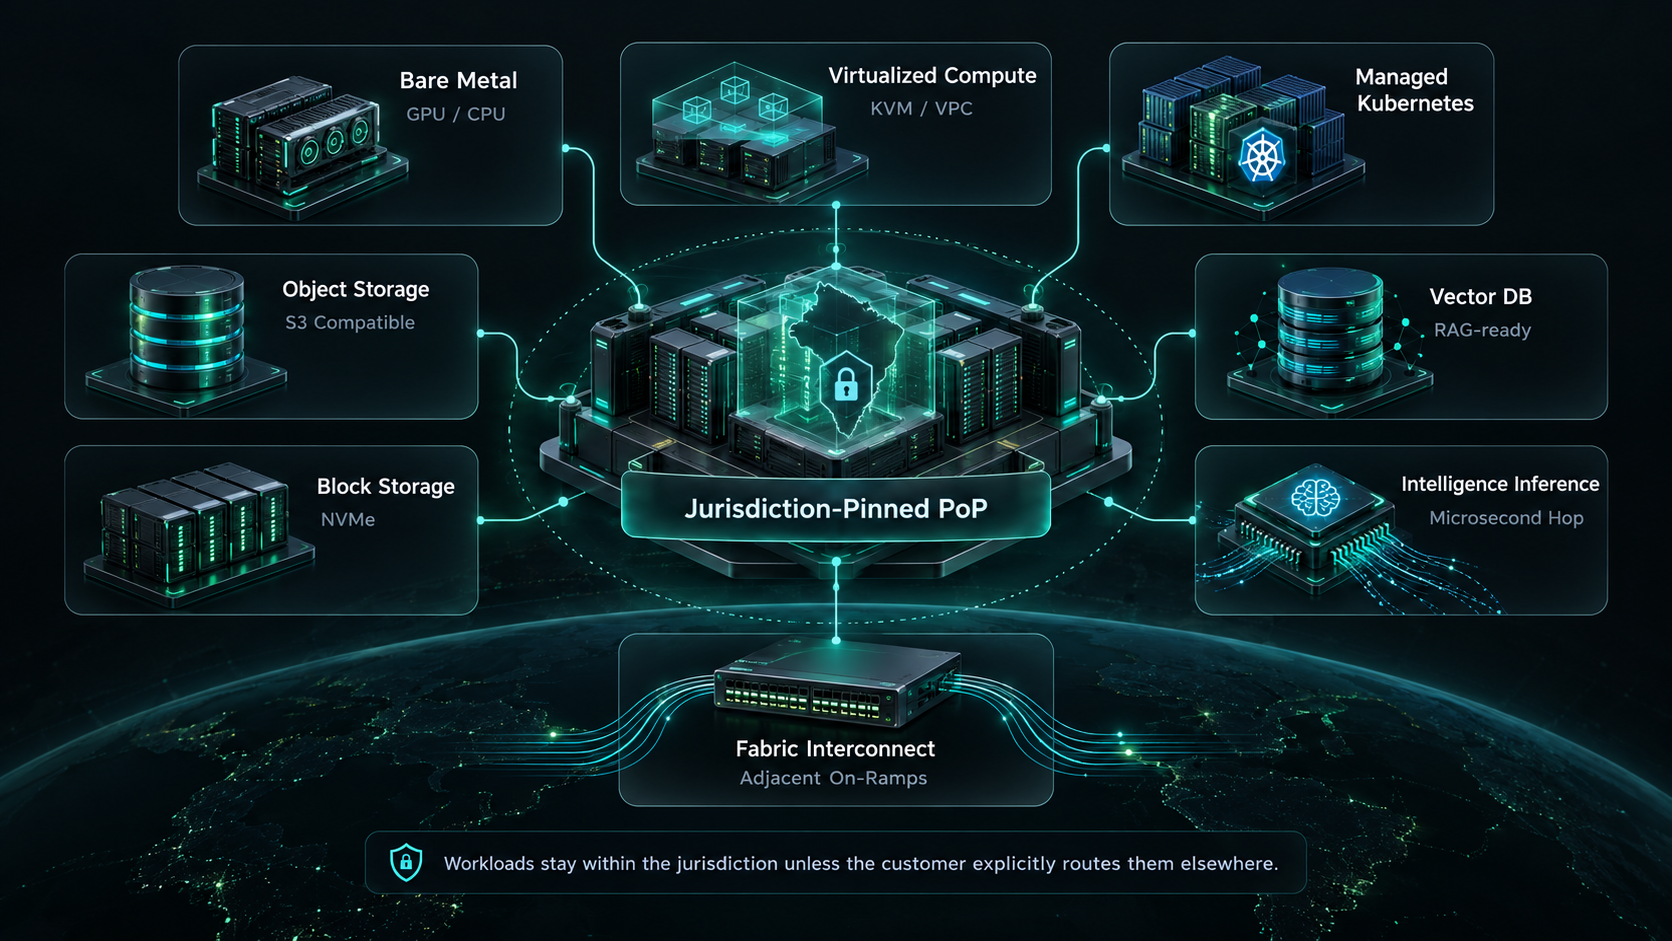
architectureHow Compute fits together.
A schematic view of the compute, storage, and platform dependencies inside a jurisdiction-pinned Veltrix PoP.
whait it isThe technical reality.
Bare metal, virtualized compute, object and block storage, and managed Kubernetes hosted in Veltrix PoPs. Designed for low-latency adjacency to the network fabric and to the AI infrastructure rather than for hyperscaler-style volume.
System Integrators
Needing managed Kubernetes for customer workloads.
AI & Data Workloads
Running RAG pipelines or vector databases adjacent to inference.
Operators
Terminating SD-WAN and SASE management planes locally.
Industrial Customers
Supporting OT and edge workloads with data-residency requirements.
what makes it differentWhere Veltrix wins.
Premium-niche, not volume
We don't try to undercut hyperscalers on $/vCPU. We charge for sovereignty and for adjacency to the rest of the platform.
Low-latency adjacency
Compute lives in the same PoPs as Fabric and Intelligence. RAG pipelines and vector stores sit microseconds from the model.
Data-resident by jurisdiction
Workloads can be pinned to a specific country. Audit trails prove it.