Veltrix Intelligence
We are not a frontier AI lab. We host, optimize and operate open-weight models in regional PoPs so that partners can deliver inference to their customers without sending tokens across foreign borders.
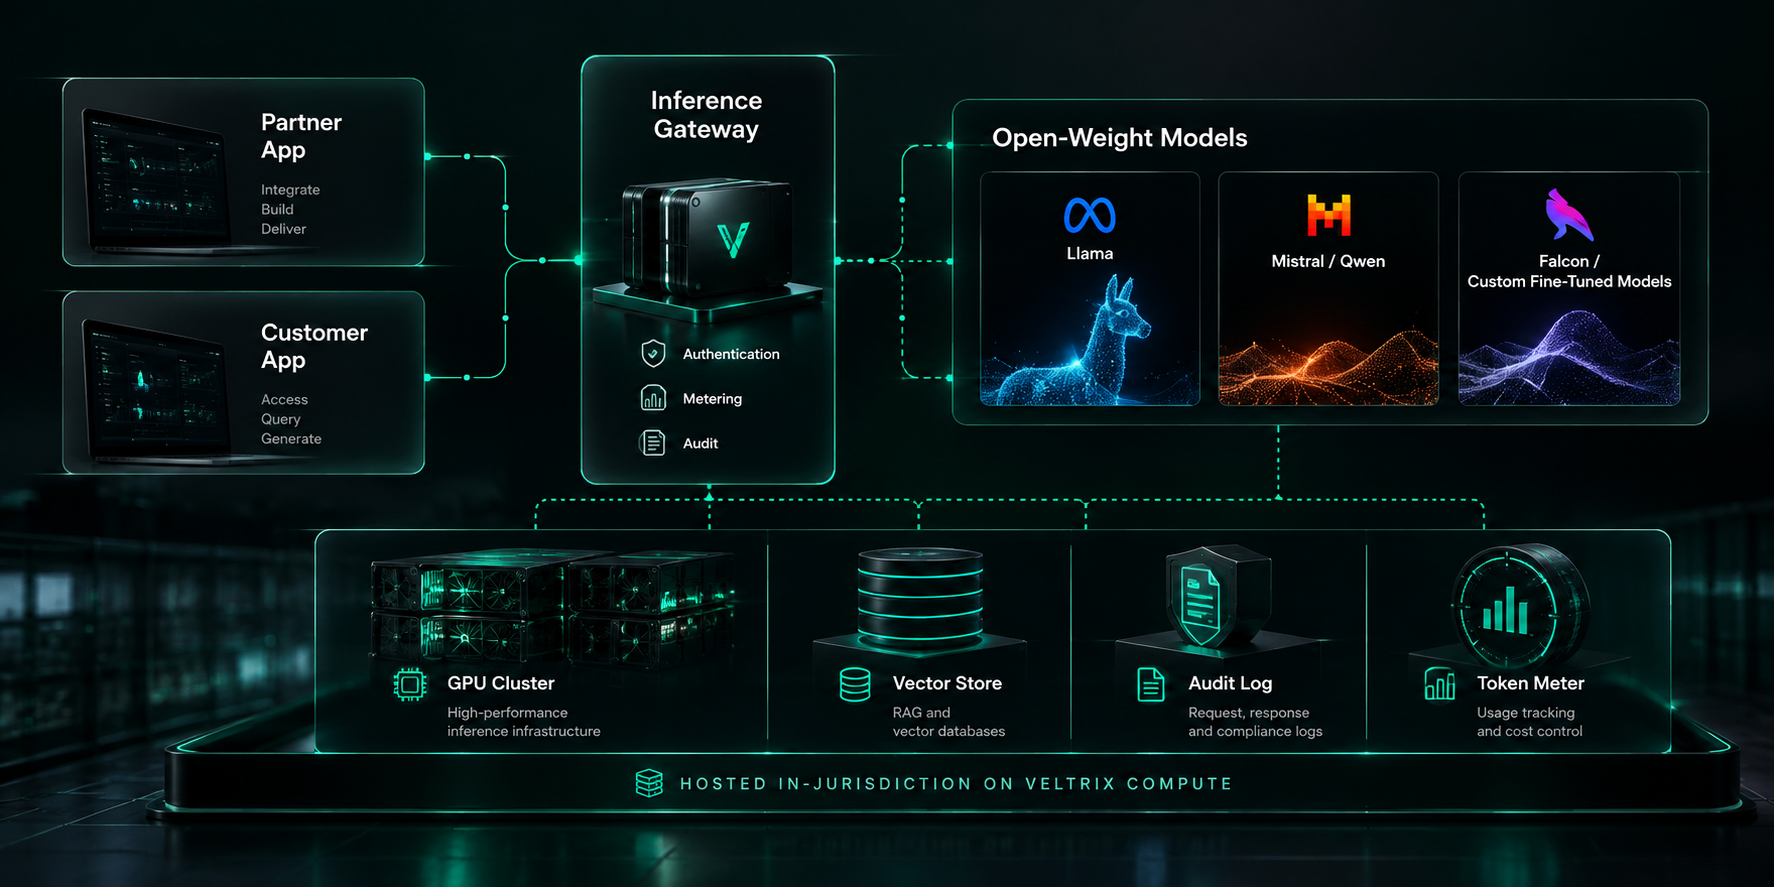
architectureHow Intelligence fits together.
A schematic view of the inference layer, model stack, data services, and partner integration points.
whait it isThe technical reality.
GPU-backed inference for open-weight models (Llama, Mistral, Qwen, Falcon and others), fine-tuning pipelines, vector database services, RAG infrastructure, and a metered token-factory consumption model. All in-region, all in-jurisdiction, all multi-tenant by partner.
System Integrators
Building sovereign AI services for regulated customers.
Operators
Offering AI as a B2B portfolio extension.
Governments
Deploying clinical, legal, or administrative AI on national infrastructure.
what makes it differentWhere Veltrix wins.
Regulator-first architecture
Every inference call has an auditable jurisdiction. Tokens, prompts and embeddings stay where the regulator says they must.
Open-weight, not vendor-locked
We optimize and operate the models customers can audit. No closed black-box dependency on a foreign frontier lab.
Token factory economics
Metered consumption at predictable per-million-token pricing, packaged so SIs and operators can resell with margin.